How to Build an AI Knowledge Base Your Business Can Trust
Build an AI knowledge base around trusted sources, permissions, retrieval, evidence, and a refresh loop that keeps answers useful after launch.
By Mark Wellington · October 4, 2026 · 11 min read
The short answer
A trustworthy AI knowledge base is not a folder of files connected to a chatbot. It is an operated source system with six parts: named source owners, current and approved information, permissions enforced for each user, content prepared for reliable retrieval, answers that show usable evidence, and a correction loop that updates both the source and the system. Start with one valuable question set, not every document the company owns.
What to take away
- →Start with one valuable question set and the smallest approved source collection that can answer it.
- →Assign an owner, status, effective date, and review rule to every source before an AI system can treat it as truth.
- →Preserve document permissions through ingestion and retrieval instead of flattening private material into one shared index.
- →Test retrieval and final answers separately so a polished response cannot hide a weak or irrelevant source match.
- →Turn corrections into source updates, evaluation cases, and refresh work so the knowledge base gets better instead of merely older.
Your company probably has the answer somewhere.
That is not the same as being able to find the right answer, prove it is current, show who may see it, and correct it before the next person asks.
A trustworthy AI knowledge base is an operated source system—not a folder of files connected to a chatbot. It needs named owners, approved information, user-level permissions, content prepared for retrieval, visible answer evidence, and a correction loop. Start with one valuable set of business questions and the smallest collection of sources that can answer them. Do not begin by pouring the entire shared drive into a shiny new index and hoping intelligence happens on contact.
Google Cloud’s RAG overview explains the basic pattern: retrieval finds relevant information from sources such as knowledge bases and databases, then the model uses that information to produce a grounded response. It also makes the important point that irrelevant retrieval can still produce an answer that is grounded—and wrong for the question.
That distinction is the whole ballgame. The model can write beautifully. Your business still has to operate the truth underneath it.
The chatbot is the front desk; the knowledge base is the building
Most early knowledge-assistant projects begin at the visible end. Someone sees a useful chat experience and says, “Could we connect this to our documents?”
Yes. But “our documents” is doing heroic amounts of work in that sentence.
Which documents? The approved policy or the draft with three comments still open? The current service guide or the version an employee downloaded last spring? The public FAQ or the internal exception notes? The file everyone can read or the folder only finance should see?
A chat box can make a messy information estate feel organized for about five minutes. Then somebody asks a consequential question, receives an answer assembled from stale material, and discovers that fluent is not a synonym for governed.
The useful project is not “put AI on the drive.” It is “create a dependable path from a business question to an approved answer.”
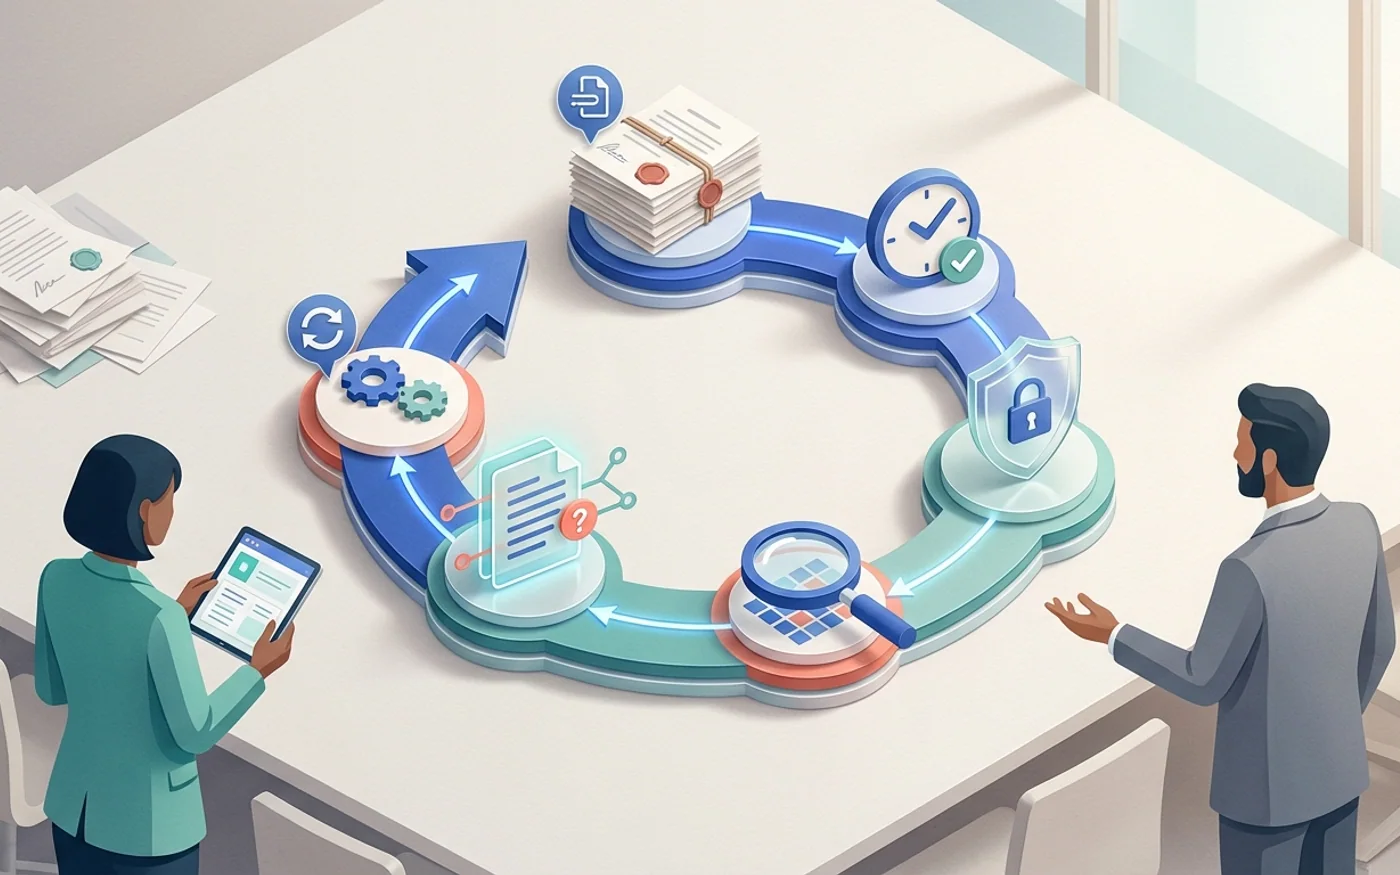
That path is the Trusted Answer Loop.
Build the six parts of the Trusted Answer Loop
The loop gives a business owner, operator, and builder six decisions they can inspect together. It is deliberately technology-neutral. You can implement it with a managed search product, a custom retrieval application, an existing collaboration platform, or a careful combination. The operating questions do not disappear when the vendor changes.
1. Question boundary: choose the job before the library
Start with the questions the system should answer and the people it should help.
“Answer anything about the company” is not a job. “Help service coordinators answer current questions about approved offerings, service areas, intake requirements, and escalation rules” is a job you can design.
Write down:
- the intended user;
- the questions that belong inside the first version;
- the decision or task the answer supports;
- the consequence of a bad answer; and
- the questions that must go to a person.
This immediately shrinks the source collection. A coordinator answering intake questions probably does not need archived proposals, payroll files, or every meeting transcript since the invention of video calls.
The smaller boundary also improves testing. You can assemble representative questions, expected sources, and unacceptable failure modes before anyone argues about vector databases over lunch.
2. Source authority: decide which file gets to be true
Every source admitted to the knowledge base needs a business owner and a status.
At minimum, record:
| Source field | The decision it answers |
|---|---|
| Owner | Who is accountable for this information? |
| Status | Is it draft, approved, retired, or superseded? |
| Effective date | When did this version become valid? |
| Review rule | When must someone inspect it again? |
| Scope | Which team, service, location, or customer type does it cover? |
| Replacement | Which newer source wins if this one conflicts? |
Without that record, the retrieval system may treat a polished old PDF and a plain current note as equally authoritative. It is not being careless. You never gave it the business rule.
Source authority is also where you remove duplicates, resolve contradictions, and stop treating tribal knowledge as a charming cultural feature. If two experienced employees answer the same question differently, indexing both answers does not solve the disagreement. It makes the disagreement available at machine speed.
3. Permission boundary: let the user retrieve only what the user may read
The knowledge base should not become a side door around the systems that already control access.
Microsoft’s Azure AI Search access-control guidance describes query-time controls that compare the caller’s identity with permission metadata captured during indexing. The feature it documents is currently in preview, but the design principle travels well: the answer path should respect the caller’s identity and the source’s permission boundary.
That means deciding:
- which identity the application uses;
- whether results are filtered for the individual, role, group, or tenant;
- how permission changes reach the index;
- how quickly revoked access stops producing results; and
- what evidence confirms that restricted sources stayed restricted.
Do not solve this by creating one giant “AI readable” folder unless every intended user genuinely has permission to read everything inside it. Convenience is not an access model.
4. Retrieval readiness: prepare information to be found in useful pieces
Humans use layout, headings, tables, repetition, and context to understand a document. A retrieval pipeline has to preserve enough of that structure to return the right passage for a specific question.
You do not need to become a retrieval engineer to ask the right questions:
- Does the extracted text match what a person sees?
- Do headings stay attached to the paragraphs they explain?
- Are tables understandable after extraction?
- Are separate products, regions, or effective dates tagged?
- Does one retrieved passage contain enough context to stand on its own?
- Can the system prefer the approved replacement over the retired source?
This is where “we uploaded the files” collides with reality. A twelve-page policy may need sensible sections. A scanned document may need reliable text extraction. A giant spreadsheet may need a structured query instead of being flattened into prose. A source with three different audiences may need metadata that narrows retrieval before the model ever sees it.
Test retrieval separately from writing. For each representative question, inspect the passages the system found. If the useful source is missing, the model never had a fair chance. If the wrong source appears first, a polished answer can make the retrieval failure harder to notice.
5. Answer evidence: make trust inspectable
A useful business answer should show enough evidence for the user to understand where it came from and what to do next.
That may include the source title, relevant passage, effective date, owner, or a direct link into the approved record. The exact presentation depends on the job. A quick internal lookup may need a simple citation. A consequential recommendation may need the supporting sources, assumptions, and an explicit human decision.
The OWASP guidance on vector and embedding weaknesses warns that weak access controls, unvalidated sources, poisoned content, and conflicting knowledge can create leakage or manipulated answers. Its practical advice includes permission-aware stores, trusted-source validation, classification, monitoring, and retrieval logs.
For a business owner, that translates into a blunt rule: do not evaluate only whether the answer sounds right. Check whether the right source was retrieved, whether the user was allowed to see it, and whether the final answer stayed inside the evidence.
Use three separate checks:
- Retrieval: Did the system find the approved information?
- Grounding: Does the answer accurately reflect that information?
- Usefulness: Does the answer help the intended person complete the real task?
A response can pass two and fail the third. That is why one average “quality score” can hide the thing you actually need to fix.
6. Correction loop: turn bad answers into better operations
Every production knowledge base gets questions it cannot answer cleanly. The difference between a useful system and a slowly decaying demo is what happens next.
Give users a clear way to flag:
- an incorrect answer;
- a correct answer supported by the wrong source;
- missing or outdated information;
- a permission concern;
- a confusing question the system misread; or
- a case that should always reach a person.
Then route that signal to an owner. The fix might be a source correction, a metadata change, a retrieval adjustment, a permission update, a better instruction, or a new evaluation case. Do not automatically rewrite source material from user feedback. A complaint is evidence to review, not instant permission to edit the company’s truth.
NIST’s Generative AI Profile recommends documenting data provenance, evaluating data quality and integrity, comparing outputs with defined guidelines, and using structured feedback to detect shifts after deployment. You do not need the vocabulary of a standards document in the user interface. You need the operating habit behind it: know where information came from, test what the system does with it, and feed real corrections back into the next version.
Start with a question pack, not a migration project
The first release should feel almost suspiciously small.
Choose one user group and collect a representative question pack from real work. Include ordinary questions, ambiguous language, missing context, outdated terminology, conflicting sources, restricted information, and requests that should trigger a handoff. Keep adding cases until the pack reflects the work you are actually willing to support; do not inflate it to create an impressive test count.
For each question, record:
- the approved source or sources;
- the essential facts the answer must contain;
- the facts it must not invent;
- the permission context;
- the acceptable response or handoff; and
- the person who can judge the result.
That packet becomes useful long before software appears. It exposes missing documentation, conflicting ownership, and fuzzy policies while they are still inexpensive to discuss.
Then build the smallest end-to-end loop: approved source, enforced permission, retrieval, answer, evidence, feedback, correction, refresh. A system that handles one valuable question set well teaches you more than a universal assistant that fails creatively across the whole company.
Do not confuse a bigger context window with a cleaner truth
Modern models can accept a lot of information. That does not make every information problem a context-size problem.
More material can still contain stale policies, duplicated instructions, private records, conflicting dates, and documents with no clear owner. Long context can be useful. Retrieval can be useful. Structured queries can be useful. None of them decides which source should win on behalf of the business.
If you are still choosing between retrieval and learned behavior, use the RAG vs. fine-tuning decision guide. If you are preparing a complete application for real users, use the production AI checklist. The Trusted Answer Loop sits between those decisions: it makes the knowledge path fit to operate, whichever technical components you choose.
Build an answer system people can challenge
Trust does not come from making the assistant sound more certain. It comes from making the system easier to inspect, correct, and own.
Start with one question set. Name the sources that are allowed to be true. Preserve permissions. Test what gets retrieved before admiring what gets written. Show the evidence. Turn corrections into better sources and better tests.
That is how an AI knowledge base becomes more than a demo with excellent manners.
If you want to turn trusted business knowledge into a useful internal application, customer tool, or decision-support product, explore custom AI software development. I can help define the first job, design the permission and retrieval path, build the evaluation set, and create an operating loop your team can understand after launch.
References
- [S01] What Is Retrieval-Augmented Generation (RAG)? — Google Cloud, Current first-party overview; accessed October 4, 2026. Accessed 2026-10-04.
- [S02] Query-Time ACL and RBAC Enforcement in Azure AI Search — Microsoft Learn, Current official guidance; accessed October 4, 2026. Accessed 2026-10-04.
- [S03] LLM08:2025 Vector and Embedding Weaknesses — OWASP GenAI Security Project, 2025. Accessed 2026-10-04.
- [S04] Artificial Intelligence Risk Management Framework Generative Artificial Intelligence Profile — National Institute of Standards and Technology, July 2024. Accessed 2026-10-04.