AI Agent Guardrails: A Practical Checklist for Business Owners
Use a practical AI agent guardrails checklist to limit data, tools, actions, approvals, failures, and evidence before an agent gets real access.
By Mark Wellington · August 19, 2026 · 10 min read
The short answer
AI agent guardrails are the technical and operating boundaries that control what an agent may access, decide, and do. Before an agent receives real business access, define one approved job, the data it may use, the tools it may call, the actions it may take, the conditions that require approval or a stop, and the evidence people need to review what happened. Prompts are only one layer; dependable guardrails also require permissions, validation, monitoring, and a recoverable human handoff.
What to take away
- →Define the agent's job and prohibited work before connecting data or tools.
- →Grant the smallest useful permission envelope, separating read, draft, recommend, and act capabilities.
- →Require approval for consequential or hard-to-reverse actions, with explicit retry and stop limits.
- →Treat prompt injection as an access-control problem as well as a model-behavior problem.
- →Keep logs, alerts, samples, and rollback evidence useful enough for a human owner to intervene.
An AI agent stops being an interesting demo the moment you give it a password, a customer record, or a button that changes something.
AI agent guardrails are the boundaries that control what the agent may access, decide, and do. Before it touches real work, define one approved job, the data it may use, the tools it may call, the actions it may take, the moments that require approval or a stop, and the evidence a human owner needs afterward.
A careful prompt helps. It is not the whole control system. You also need permissions, validation, monitoring, and a handoff that works when the agent runs out of road.
NIST’s AI Risk Management Framework Core puts the durable pieces in plain view: define roles, document how people oversee the system, test before deployment, monitor in operation, and keep contingency processes for failures. Your implementation does not need to resemble a federal filing cabinet. It does need to answer those operating questions.
A polite agent with broad access is still an agent with broad access
Business owners often start the guardrail conversation with behavior:
- Do not say anything offensive.
- Stay on topic.
- Follow our policy.
- Ask before doing something important.
Those instructions matter. They are also words presented to a system that works with more words. A prompt can influence behavior, but it cannot replace the access controls enforced by the application, the connected tool, and the business account.
Imagine an agent that reviews new service inquiries. It may need to read a form, look up an approved service area, draft a response, and suggest the next step. That does not automatically mean it should export the whole CRM, edit customer records, send every message without review, or keep retrying when a downstream system behaves strangely.
The useful question is not, “Do we trust the AI?”
The useful question is, “What is the smallest useful world this agent needs in order to do this job?”
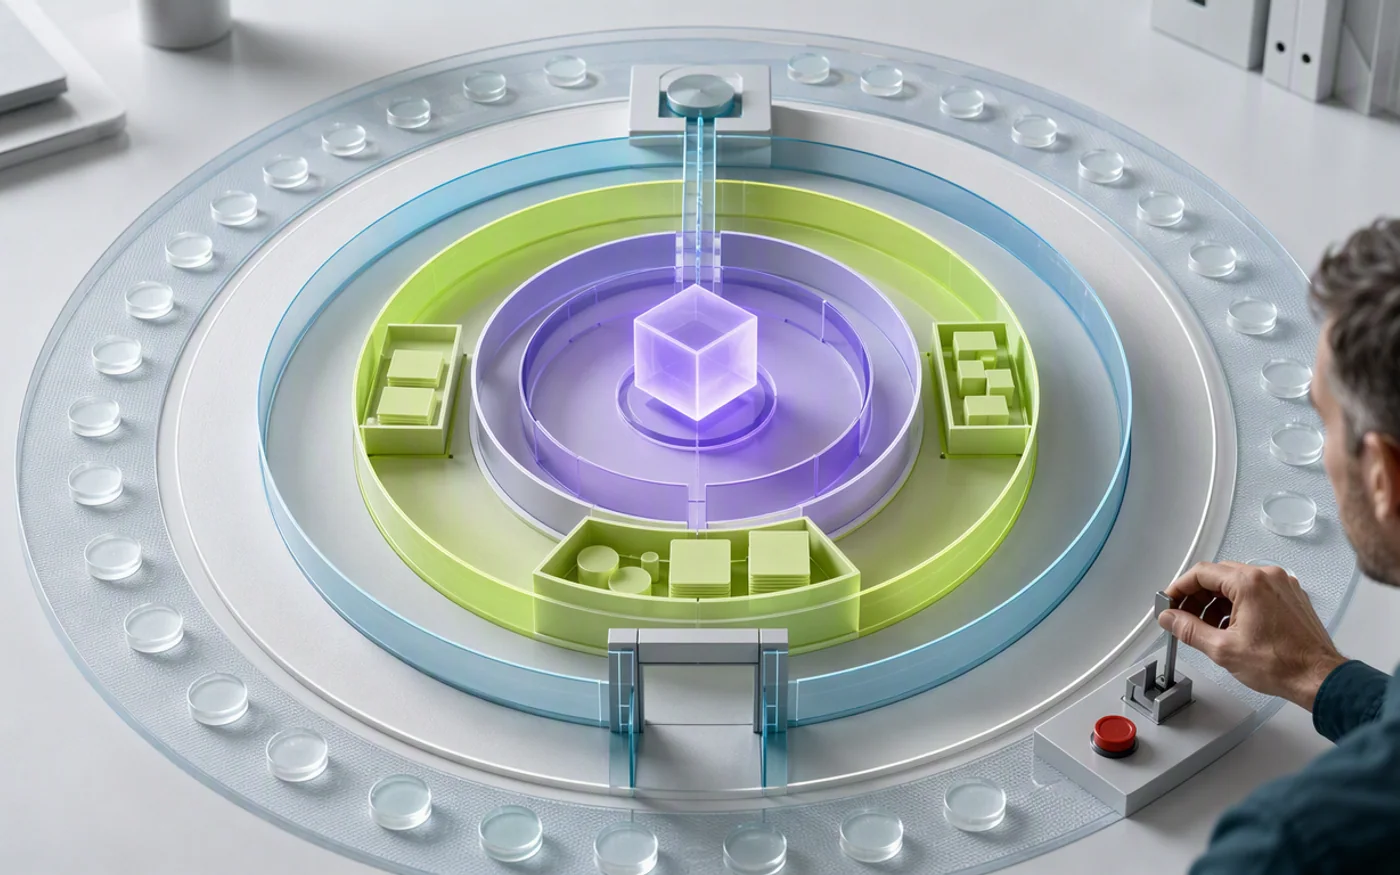
That world is the Agent Action Envelope.
Draw the six boundaries of the Agent Action Envelope
The envelope turns a vague promise to “add guardrails” into six decisions a business owner, operator, and builder can inspect together. Each boundary should be enforceable where possible and written in language the person responsible for the workflow can understand.
1. Job boundary: name the work and the work it must refuse
Write one sentence:
This agent helps this person complete this job using these inputs, and it must stop when these conditions appear.
“Help with sales” is too foggy. “Classify inbound inquiries by approved service and location, draft a reply from current service information, and send uncertain or sensitive cases to the sales coordinator” is something you can design and test.
Add the prohibited work next to the approved work. The inquiry agent may not quote custom pricing, promise availability, change contract terms, or make a judgment about a person that belongs with a qualified employee.
This boundary keeps the system useful without quietly turning one successful task into a wandering digital job description.
2. Data boundary: limit what the agent can see and remember
List the exact sources the agent may read. Then separate data it needs from data that happens to live nearby.
If an agent needs the service requested and the customer’s preferred contact method, do not automatically hand it every note, payment record, and historical export in the account. If it needs current policy material, give it the approved source rather than an open drive full of drafts and abandoned versions.
The data boundary should cover:
- approved source systems and folders;
- fields the agent may and may not receive;
- retention, memory, and deletion behavior;
- sensitive information that triggers a handoff; and
- the person who approves a new source.
Least access is not bureaucracy. It reduces the number of ways an ordinary mistake or a hostile instruction can become an expensive one.
3. Tool boundary: rate every capability before you connect it
Tools give the agent reach. Treat them individually.
OpenAI’s practical guide to building agents recommends rating tools by factors such as read versus write access, reversibility, required account permissions, and financial impact. That gives you a much better control surface than one master switch labeled “agent access.”
Use three simple lanes:
| Tool lane | Typical capability | Default control |
|---|---|---|
| Read | Retrieve an approved record or policy | Allow within the job and data boundary |
| Prepare | Draft a message, update, or proposed action | Save for review; do not execute |
| Act | Send, publish, purchase, delete, change, or commit | Require an explicit rule, approval, and recovery path |
Create a separate credential or service identity when the platform supports it. Give it only the scopes required for the job. “It uses the owner’s login” is not a shortcut; it is the disappearance of a boundary.
4. Action boundary: validate the move, not just the sentence
An agent may produce a perfectly reasonable explanation and still prepare the wrong action.
Validate important action details with deterministic software before execution. Confirm that the customer record exists, the amount stays inside an approved limit, the recipient matches the active case, the requested operation is allowed, and the same event has not already been processed.
The current OWASP Top 10 for Agentic Applications names goal hijacking, tool misuse, identity and privilege abuse, poisoned components, and cascading failures among the major agentic risks. The practical business lesson is simple: a well-written response is not evidence that the next tool call is safe.
For each action, record:
- allowed values and limits;
- duplicate protection;
- preconditions that must be true;
- whether the action is reversible;
- what the user sees before approval; and
- how the system confirms completion.
This is where ordinary software engineering earns its keep. The model proposes. The application checks. The connected service enforces.
5. Approval and stop boundary: decide when the agent must give the wheel back
“Ask a human when necessary” is not a rule. Necessary according to whom, visible where, and with what context?
Name the triggers before launch. Useful examples include:
- missing or contradictory required information;
- a request outside the approved job;
- a sensitive person, account, or data type;
- an irreversible or financially meaningful action;
- repeated tool failure;
- a result that fails validation; and
- uncertainty about the user’s actual intent.
The handoff should include the original request, the information used, what the agent tried, what failed, and the decision the person must make. A red badge with no context is not human oversight. It is a scavenger hunt with urgency styling.
Set retry limits and stop conditions too. An agent that keeps trying can turn one timeout into duplicate messages, repeated charges, or a growing stack of corrupted records. When a dependency is uncertain, stopping is a feature.
6. Evidence boundary: keep enough truth to operate the system
The owner needs to see what happened without reconstructing the event from six dashboards and a hunch.
Keep evidence proportionate to the job:
- the request and approved business context;
- the source and tool access used;
- the proposed and executed action;
- approvals, rejections, and human changes;
- failures, retries, and stop events;
- the agent, model, prompt, or workflow version; and
- the final outcome available to the system.
Then decide who reviews it, how often, and what causes a change. Logs that nobody can interpret are storage. Logs connected to sampling, alerts, incident review, and improvement are an operating control.
Prompt injection is why access beats optimism
An agent does not only read your instructions. It may read emails, documents, web pages, tickets, database records, and tool results created by other people. Any of that content can contain instructions that conflict with the real job.
Anthropic’s trustworthy-agents guidance describes prompt injection as malicious instructions hidden inside content an agent processes. It also makes the uncomfortable point that no single defense guarantees protection. The more open the environment and the more tools the agent can use, the larger the possible consequence.
That is why the envelope matters. Detection can help identify a suspicious instruction. The deeper defense is making sure the agent still lacks the data, permission, or tool needed to turn that instruction into a damaging action.
Use layers:
- Separate trusted system instructions from untrusted content.
- Limit sources and sanitize or label external material.
- Restrict tool permissions and action parameters.
- Require approval where the consequence justifies it.
- Monitor unusual access, sequences, destinations, and failures.
- Make stopping and revoking access fast.
No layer gets to declare the others unnecessary.
Test the guardrails with awkward work, not polite examples
Before launch, create a small test packet that tries to leave the envelope.
Include a normal request, missing information, contradictory information, an out-of-scope request, an untrusted document containing hostile instructions, a duplicate event, a unavailable tool, a prohibited destination, and a consequential action without approval.
For every case, write the expected behavior first:
- proceed;
- prepare but do not act;
- ask one specific question;
- hand off with context;
- refuse; or
- stop and alert the owner.
Run the test again when permissions, tools, models, prompts, integrations, or business rules change. Guardrails are not a laminated certificate earned at launch. They are part of the product.
If you have not yet decided whether the job needs an agent at all, start with the AI agent vs. workflow automation decision tree. If you are preparing the complete application for release, use the broader production AI checklist. The Agent Action Envelope lives between those decisions: you chose an agent, and now you must decide how much world it receives.
Give the agent enough room to work—and no room it did not earn
Good guardrails do not reduce an agent to a chatbot that asks permission before moving a comma. They create a useful lane: routine, low-consequence work can flow; ambiguous or consequential work reaches a person; suspicious content hits containment; and failures leave evidence instead of folklore.
Start with one job. Draw the six boundaries. Test the attempts to escape them. Expand permissions only when real operating evidence earns the change.
If you are building an agent that will connect to business data and take real actions, explore custom AI software development. I can help define the job, design the permission and approval model, build the application controls, test ugly cases, and give the operating owner the visibility needed after the demo ends.
References
- [S01] AI Risk Management Framework Core — National Institute of Standards and Technology, Current AI RMF Core; accessed August 19, 2026. Accessed 2026-08-19.
- [S02] A Practical Guide to Building Agents — OpenAI, Current first-party guide; accessed August 19, 2026. Accessed 2026-08-19.
- [S03] OWASP Top 10 for Agentic Applications — OWASP GenAI Security Project, December 9, 2025. Accessed 2026-08-19.
- [S04] Trustworthy Agents in Practice — Anthropic, April 9, 2026. Accessed 2026-08-19.